The Next Frontier for AI Fabrics: Scale Across Networking
As AI training workloads and frontier models continue their exponential climb to support trillions of parameters and millions of AI accelerators, a...
4 min read
As AI training workloads and frontier models continue their exponential climb to support trillions of parameters and millions of AI accelerators, a harsh reality is setting in. Physical space constraints and restrictive power availability are a scarcity. This introduces the new dimension of pragmatic reality to move from centralized vertical stacks to horizontal distributed scale-across AI fabrics. Basically, scale-across transforms the long-distance extension of the local scale-up and scale-out AI cluster to achieve high compute density across geographies.
Scale-Across with 7800 AI Spine
The scarcity of compute capacity and megawatts of power mandates that the AI infrastructure must be designed thoughtfully at scale. The Arista 7800 platform continues to be the ideal flagship spine for scale-across applications, providing traffic isolation, contextual routing and security. Scale-across AI innovations deliver many L2/L3 switching features for programmable, deterministic routing, SRv6 multiplane forwarding, multi-tenancy traffic engineering, and load-balancing across regions capable of providing near-instantaneous (tens of uSec) recovery in the event of transient congestion, packet loss, or a physical failure of AI clusters, independent of location. It uses SRv6, or segment routing, which isn't new, but using it to load-balance an AI fabric is the game changer. In SRv6, the sender tags each packet with a stack of SRv6 segment ID's, dictating the exact path the packet will take. The system then uses real-time congestion signaling to dynamically shift packets away from hotspots. Leveraging the reliable, state-sharing Arista EOS as a single, unified operating system, this SRv6 intelligence is supported all the way from the scale-out fabric to the long-distance, scale-across routing. Our customers now get the combination of high scale/performance, reliability, and operational rigor that Arista is known for while connecting to different forms of coherent optics such as ZR/ZR+, and DWDM transport.
Reliable Multi-Site High-Performant Foundation
Stretching an AI compute fabric across distributed geographies isn’t just a matter of provisioning a standard Data Center Interconnect (DCI) link. AI workloads demand massive, highly synchronized, and bursty collective communication flows. If long-haul communications aren’t explicitly architected for these patterns, it becomes a structural bottleneck that severely degrades AI performance. Scale-across AI fabrics are designed not only to optimize performance in best case scenarios, but also to react gracefully when plans go awry and provide highly reliable, secure and uncompromised communication, as shown in Figure1 below.
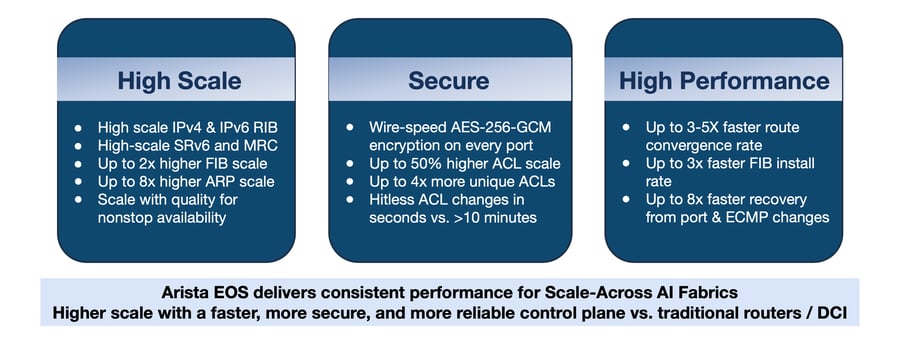
Figure 1: Arista Scale-Across is based on foundational principles of uncompromised scale, security and reliability
A typical scale-across AI network is designed for reliable, consistent, lossless packet transport, paired with real-time analytics to measure and validate performance. It means optimizing for consistently low end-to-end latency, with intelligent traffic engineering to steer workloads to local vs. remote sites, while incorporating buffering insurance to protect latency by avoiding packet loss during transient congestion. Scale-across builds upon the “hope for the best but prepare for the worst” in demanding AI networks.
“REACH” with Scale-Across Fabrics
Arista enables optimized scale-across fabrics that extend REACH for AI workloads through a combination of foundational tenets that together deliver an essential suite of features for AI operators designing for consistent scale, performance and availability. Operating long-haul, scale-across networks without the protection of deep packet buffering is akin to riding a bike down a steep hill without a helmet. Arista’s REACH solution for scale-across AI fabrics includes:
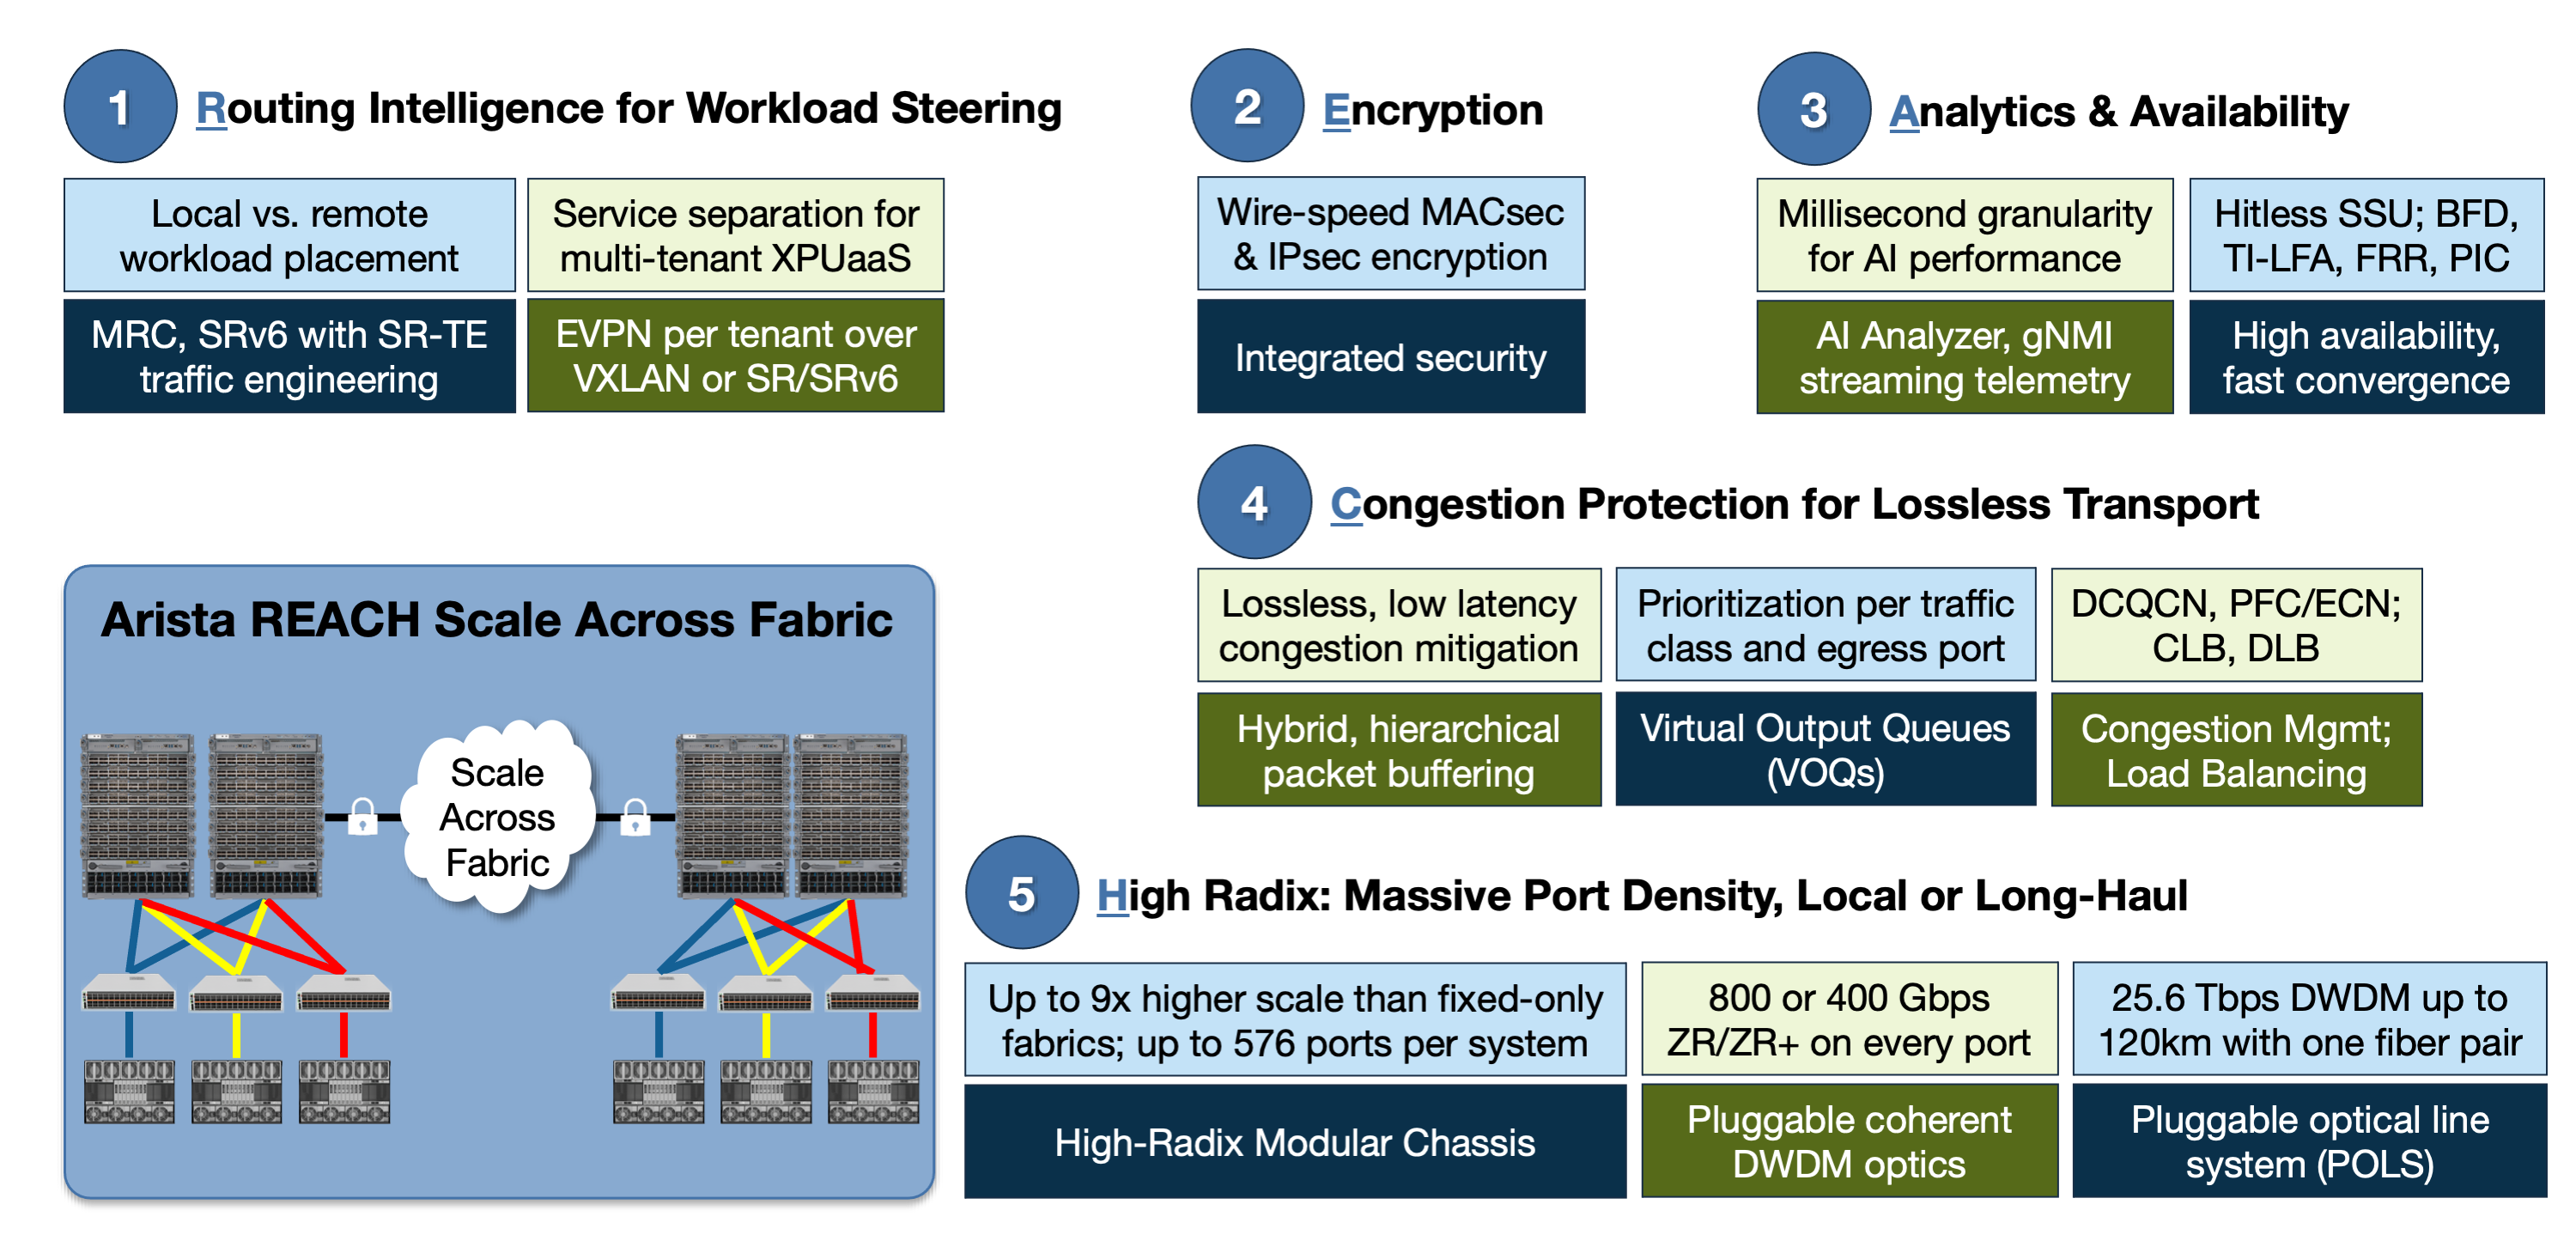
Figure 2: Arista REACH for Scale-Across AI Fabrics
Summary: Purpose-Built Network For AI Models
Not all routing is created equal. Legacy routers have many challenges with scale and recovery/convergence time of minutes, which do not meet the requirements of modern AI model routing. Arista’s modern AI routing was natively designed for AI/cloud-scale deployment using purpose-built software principles. It leverages merchant silicon designed for high-speed, lossless AI fabrics with fine-grained insights into AI performance and real-time availability of resources. Based on our philosophy of ONE operating system (EOS) across the entire Arista Etherlink AI portfolio for scale-up, scale-out and scale-across AI fabrics, the network brings consistent throughput for high utilization of expensive compute. Scale-across is designed to deliver uncompromised scale, security and reliability. Welcome to the new world of Arista’s scale-across REACH strategy for global scale without compromise.
References
Powering Next-Gen AI Clusters: High-Performance Networking with AMD and Arista
As AI training workloads and frontier models continue their exponential climb to support trillions of parameters and millions of AI accelerators, a...
Two decades into our journey, quality remains Arista's absolute top priority: networking you can count on. Thus, product security is a first...

 Brendan Gibbs: Jul 21, 2026, 5:59:59 AM
The industry has spent the last several years obsessed with securing the cloud. Secure Access Service Edge (SASE), as popularized by Gartner1, has...